
429 Too Many Requests or 503 Service Overloaded. To avoid 429s, you need to stay below our adaptive rate limits. To reduce the likelihood of 503s, you can upgrade to Priority tier.
Rate limits are per account and per model — there is no single account-wide token pool. Each model has its own TPM limits, and each model’s adaptive limit grows, shrinks, and resets based only on your usage of that model. Using one model does not consume another model’s limit, and hitting a limit on one model does not rate limit your traffic to other models.
What are your rate limits?
There are three metrics we use to rate limit each account, separately for each model:- Total Prompt TPM — input tokens per minute (cached + uncached).
- Uncached Prompt TPM — uncached input tokens per minute.
- Generated TPM — output tokens per minute.
429s for that model only — your other models keep their own, unaffected Total Prompt TPM limits.
Base adaptive rate limit ceilings depend on the model’s total parameter count. Smaller models get higher base ceilings:
| Tier | Total parameters | Total Prompt TPM | Uncached Prompt TPM | Generated TPM |
|---|---|---|---|---|
| Small | < 800B | 216M | 54M | 2.16M |
| Medium | 800B – < 1.6T | 43.2M | 10.8M | 432k |
| Large | ≥ 1.6T | 21.6M | 5.4M | 216k |
Models by tier
Models not listed here are tiered by total parameter count using the thresholds above.
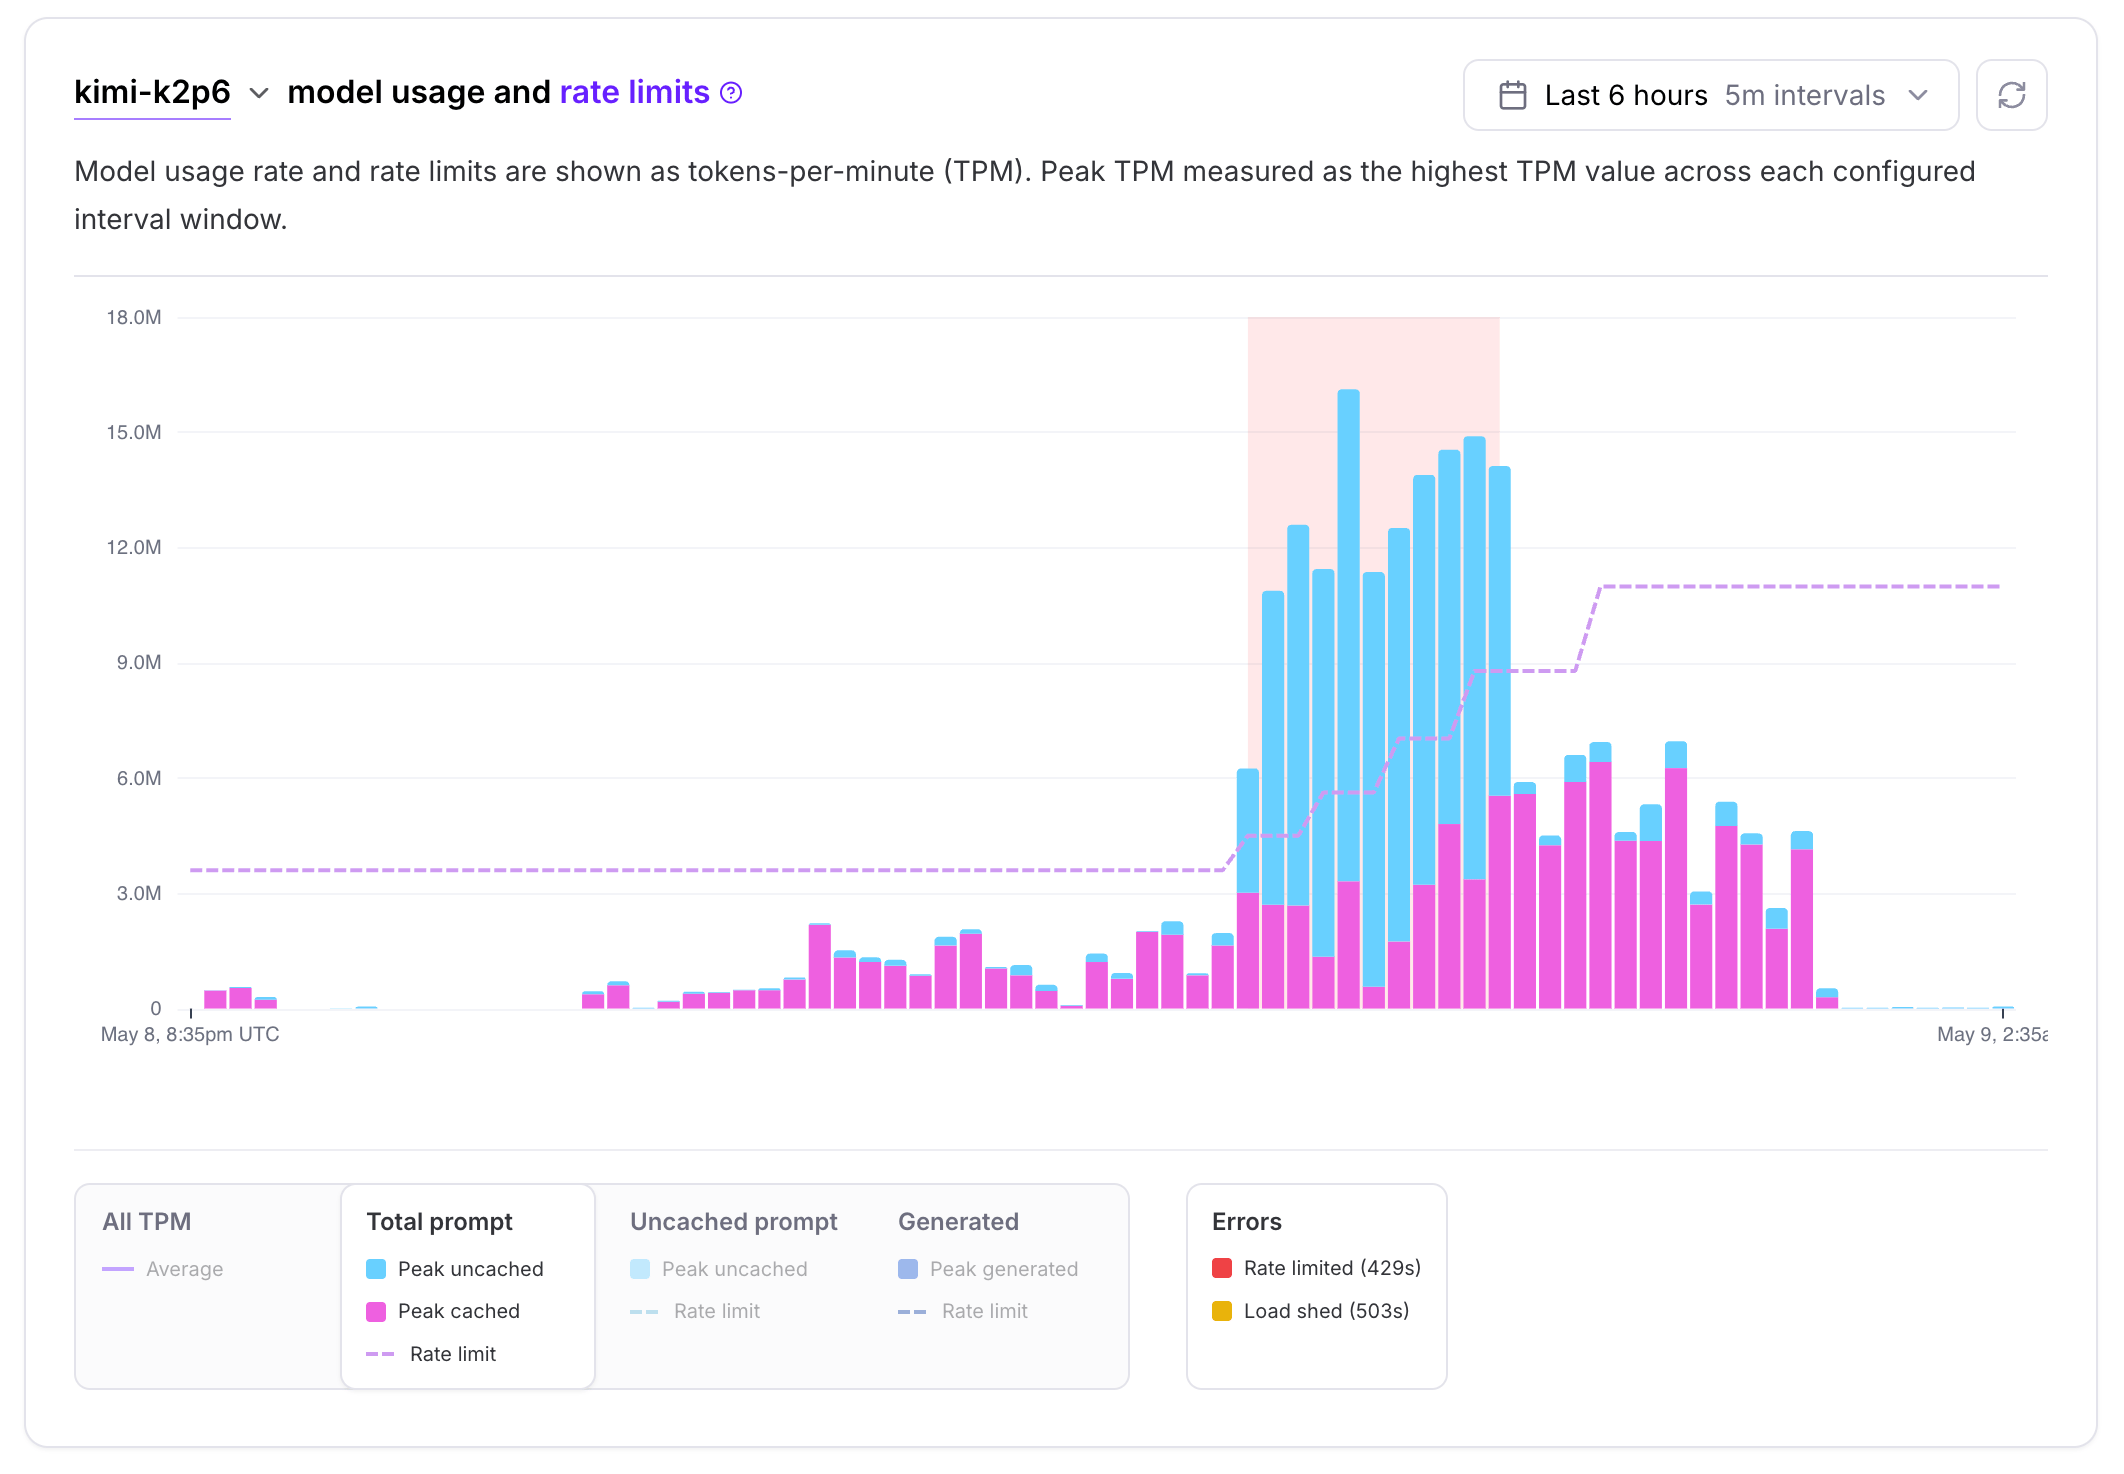
Based on your usage, your adaptive limits will grow and shrink within these base ceilings. Eligible accounts may also receive temporary capacity above the base ceiling through Elastic Burst. If your traffic ramps up too quickly, you will get 429s.
How do adaptive limits change?
Adaptive rate limiting is also per model: each model’s limit adapts independently, based only on your recent usage of that model. Ramping up one model does not raise another model’s limit, and going idle on one model does not shrink another model’s limit. Your limit for each model starts at a default value and grows in steps as you use it. If your recent one-minute usage is above 50% of your current limit, the limit increases by 25%, and no more than once every 15 minutes, until it reaches your base ceiling. If you stop using it, the limit shrinks slowly and eventually resets. Elastic Burst can move the current limit above that ceiling, and back toward it, independently of the schedule below. Each of the three metrics (Total Prompt TPM, Uncached Prompt TPM, and Generated TPM) has its own standard adaptive limit and changes on its own. Heavy usage on one metric does not change the other standard limits. Under Elastic Burst, high usage on one of these metrics can reduce burst capacity on the others.Your base ceiling
The base ceiling is the highest your standard adaptive limit can grow without Elastic Burst. Two things set it:- Model size picks the row in the table above.
- Your spending tier sets how much of that row you can reach. The table shows the maximum ceilings, available at Tier 3 and above. Tiers below Tier 3 have lower ceilings.
Elastic Burst
Elastic Burst can temporarily raise an eligible account’s current limit above its base ceiling when spare capacity is available. It applies to Total Prompt TPM, Uncached Prompt TPM, and Generated TPM. For eligible accounts and models, Elastic Burst applies automatically to the existing Serverless endpoint; no request or client changes are required. That extra capacity is not guaranteed, and it can change independently of the standard schedule below. If your current limit drops, pace traffic against the new limit. For429 responses, honor the Retry-After header; if it is absent, retry with exponential backoff and jitter. Elastic Burst does not change your base ceiling or any Reserved Throughput. Elastic Burst has no separate enablement fee or burst premium. Usage is billed at your applicable Serverless token rates.
To opt out, contact your Fireworks account representative. The opt-out is account-wide and applies across all models for Total Prompt TPM, Uncached Prompt TPM, and Generated TPM.
When limits go up, down, or reset
A few details:
- A decrease is skipped if your recent usage would be at least 50% of the lower limit. This keeps the limit from dropping and then immediately climbing back up.
- With Reserved Throughput, the increase, decrease, and reset thresholds apply to usage above your reservation and to the adaptive portion of your limit. Usage within the reservation does not count toward the thresholds.
- Resets do not apply to accounts with a custom limit or a reservation for that model.
- Elastic Burst example: if your current limit is 100M TPM, Elastic Burst can raise it once your usage is above 50M TPM and spare capacity is available.
How slowly limits shrink
The steps below follow the standard Decrease row. Elastic Burst capacity can leave without waiting for these daily steps. Say your Total Prompt TPM limit is 10,000,000 and your traffic drops to a steady 1,000,000 tokens per minute:
If you stop sending traffic completely, you don’t go through these steps. After more than 72 hours with no traffic, the limit resets to the starting default.
Example: ramping up
Say your current Total Prompt TPM limit is 1,000,000.- Send more than 500,000 but less than 1,000,000 prompt tokens per minute. This keeps you above half your limit without hitting 429s.
- More than 15 minutes later, your limit rises to 1,250,000.
- Raise your traffic to match, staying between 625,000 and 1,250,000.
- Repeat until your limit stops rising.
Checking your current limit
The Serverless dashboard shows historical limit samples, not an instantaneous reading. A Serverless response can include the latest known effective limit in these headers when that limit is known. The value can lag a recent change.X-Ratelimit-Limit-Tokens-Promptfor Total Prompt TPMX-Ratelimit-Limit-Tokens-Uncached-Promptfor Uncached Prompt TPMX-Ratelimit-Limit-Tokens-Generatedfor Generated TPM
X-Ratelimit-Limit-Tokens-Cache-Adjusted-Prompt is a separate limit and does not include Elastic Burst. See response headers.
FAQ
Am I guaranteed successful responses up to my rate limit?
Am I guaranteed successful responses up to my rate limit?
No. Staying within your rate limits does not guarantee that every request succeeds. When a deployment is busy, your traffic can still be load shed, and those responses are
503 Service Overloaded. To decrease the chance of being load shed, you can use Priority tier, which is prioritized during high load.How are rate limits scoped?
How are rate limits scoped?
Rate limits — including adaptive rate limiting — are scoped per account and per model. Each model has its own TPM limits and its own adaptive limit, which grows, shrinks, and resets based only on your usage of that model. Traffic to one model does not consume, raise, or lower another model’s limits. Fast and regular model variants have separate limits. Priority tier and regular requests share the same rate limits for a given model.
How is my model's ceiling tier determined?
How is my model's ceiling tier determined?
Ceiling tiers are based on the model’s total parameter count: Small (< 800B), Medium (800B – < 1.6T), or Large (≥ 1.6T). See Model size tiers for the ceiling values and Models by tier for where each Serverless model falls.
What should I do first when I see 429s?
What should I do first when I see 429s?
Honor the response’s
Retry-After header. If it is absent, retry with exponential backoff and jitter.How do I get higher limits sooner?
How do I get higher limits sooner?
Reach out to inquiries@fireworks.ai for a custom solution if either of these applies:
- You need higher than the defaults from day one. Your launch traffic exceeds the starting limit and you can’t wait for the adaptive ramp.
- You’re ramping past the highest base ceiling. You are already at the highest account Spending Tier and the standard adaptive limit is not growing.